Flux.2 Also Ignores Everything
People talk about Flux.2 being really good at following prompts, but my recent experience has felt like the rate of adherence is still about only 50%. This is not great, particularly when the ignored parts end up being crucial for storytelling and/or continuity. This came in sharp relief when I was looking for a character LoRA to write an explainer on what weights do. I was on Civitai and found an image suitable for the weight work, and started to read the prompt.
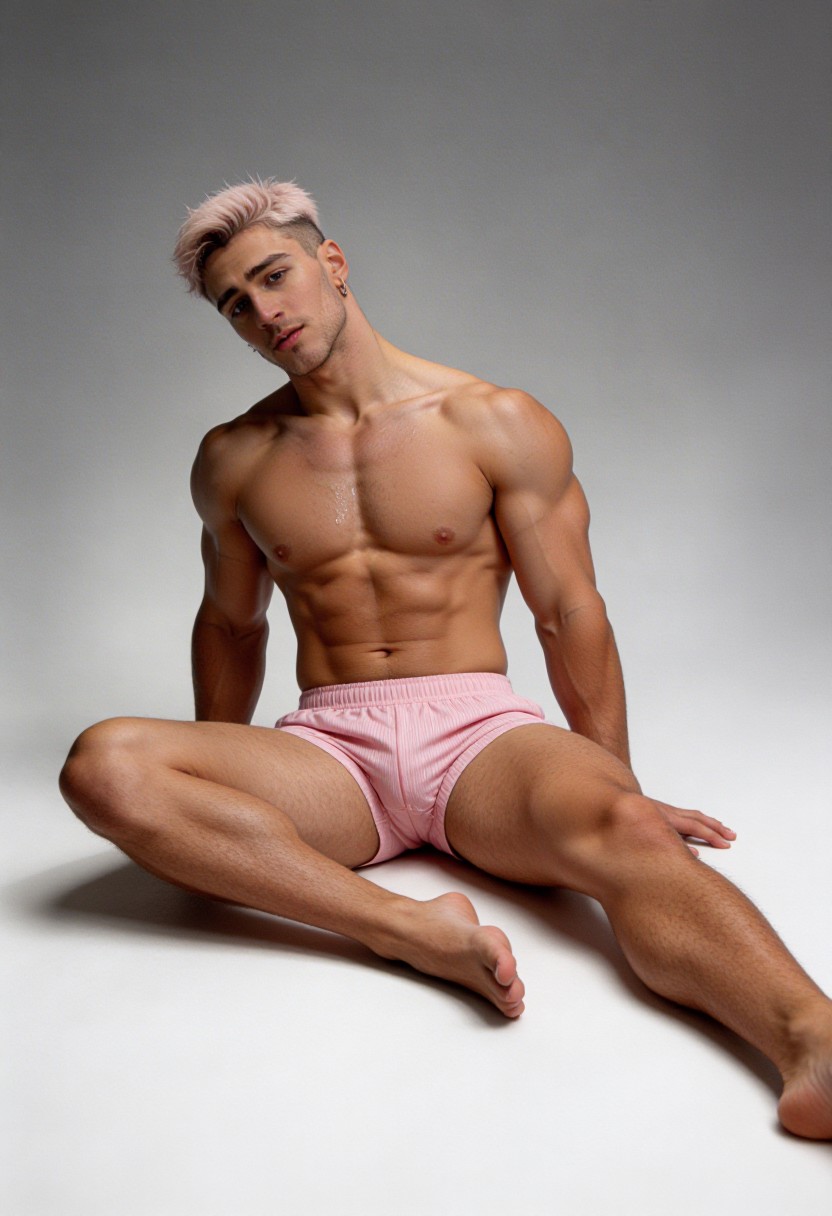
There are some problems here. First, it was not written in typical narrative Flux style, but instead it was in what I call a “semi- Danbooru2” idiom1, that is, a bunch of short concepts strung together. The nice thing about this approach is that I don’t have to do anything to distill the concepts: each comma-delimited clause is a concept.
This was 17 concepts. Listed below with “+” for present in the image, “=” for partial credit, and “-“ for not present
- = portrait photo of a muscular man sitting flat on floor legs apart,2
-
- big crotch bulge
-
- one hand behind his back supporting his weight,
- = he is wearing very short striped pink loose boxer shorts,3
-
- massive legs
- = sweaty, 4
-
- tilted angle,
-
- dutch angle,
-
- shallow depth of field,
-
- extreme chromatic aberration,
-
- volumetric fog,
-
- neon lights,
- = cinematic lighting, 5
-
- bright atmosphere,
-
- film grain,
- = high-resolution realistic detail,6
-
- charcoal grey gradient background,
In the end, this is not a great showing. Less than 20% of the concepts were definitively rendered, and over half were not there (or could never really be there.)
Now, the challenge here is that picking a prompt at random on Civitai is in no way picking a high-quality prompt. The images on Civitai are ones that the users like, and may not even reflect what their original artistic vision was. We see this in the presence of keywords that have absolutely no reflection in the final image7, likely relics of earlier exploration, or using old prompts as foundations. This re-use, while completely understandable, makes computation of “intended adherence” much more difficult.
There is still a place for the occasional “__ ignores everything,” when I find a suitable example. But, as long as I’m pulling examples from the open internet, it’s clear that at best, I am only looking at median exmaples.
But what to make of prompt adherence more broadly? Right now, I think it’s actually a red-herring. The current image models are definitely good enough for one-off images, where you can adjust the art direction on the fly. But the low adherence makes it hard to use for longer graphical story-telling. You can see this in much of the slop out their: character consistency just isn’t there. (I am reminded of a recent Youtube video essay on the Pennsylvania Railroad, extensively illustrated with UP engines.) This makes it hard to use for anything more than two or three frames. Layer so-so character consistency on top of that, and it seems nearly impossible.
So, what is to be done? I’m still exploring this, but right now, I think the answer is pastiche: one image is a combination of frontier-model rendering, coupled with in-painting, and specialized editors (e.g. face swap). Any “real” piece of GenAI “art”8 is going to be a composite of several images with a lot of spot-fixes. Until we have really good brain-computer interfaces, it’s always going to be succesive refinement.
-
This will be really useful in an upcoming effort. ↩
-
Partial credit for “legs apart” ↩
-
Partial credit for “striped” ↩
-
He’s got something wet on his chest. ↩
-
Do these prompts do anything in 2026? I would think that modern models “factor them out.” ↩
-
Not sure how much flux can do with 1152x768 render area. ↩
-
For a particularly egregious version of this, check out this guy. The middle third ↩
-
I know a lot of people say it’s not art. But photography is art. ↩